Mercity
Research

What we tried, what held up, and why.

Published papers and long-form logs of our own experiments, implementation detail included,because that is the part every other write-up leaves out and the part you need to reproduce it.

Papers

Train on prefill, monitor at decode: Using sparse autoencoders for topic monitoring

Small causal detectors on sparse autoencoder features label every token a model writes with a topic, so the label can change partway through a response. Trained on prefill, they carry over to decoding on Gemma 3 1B and 4B.

Rishikesh Mallagundla, Pranav Patel arXiv GitHub Research log

Research logs

Latest Research

Real-Time Topic Guardrails with Sparse Autoencoders: A Research Log

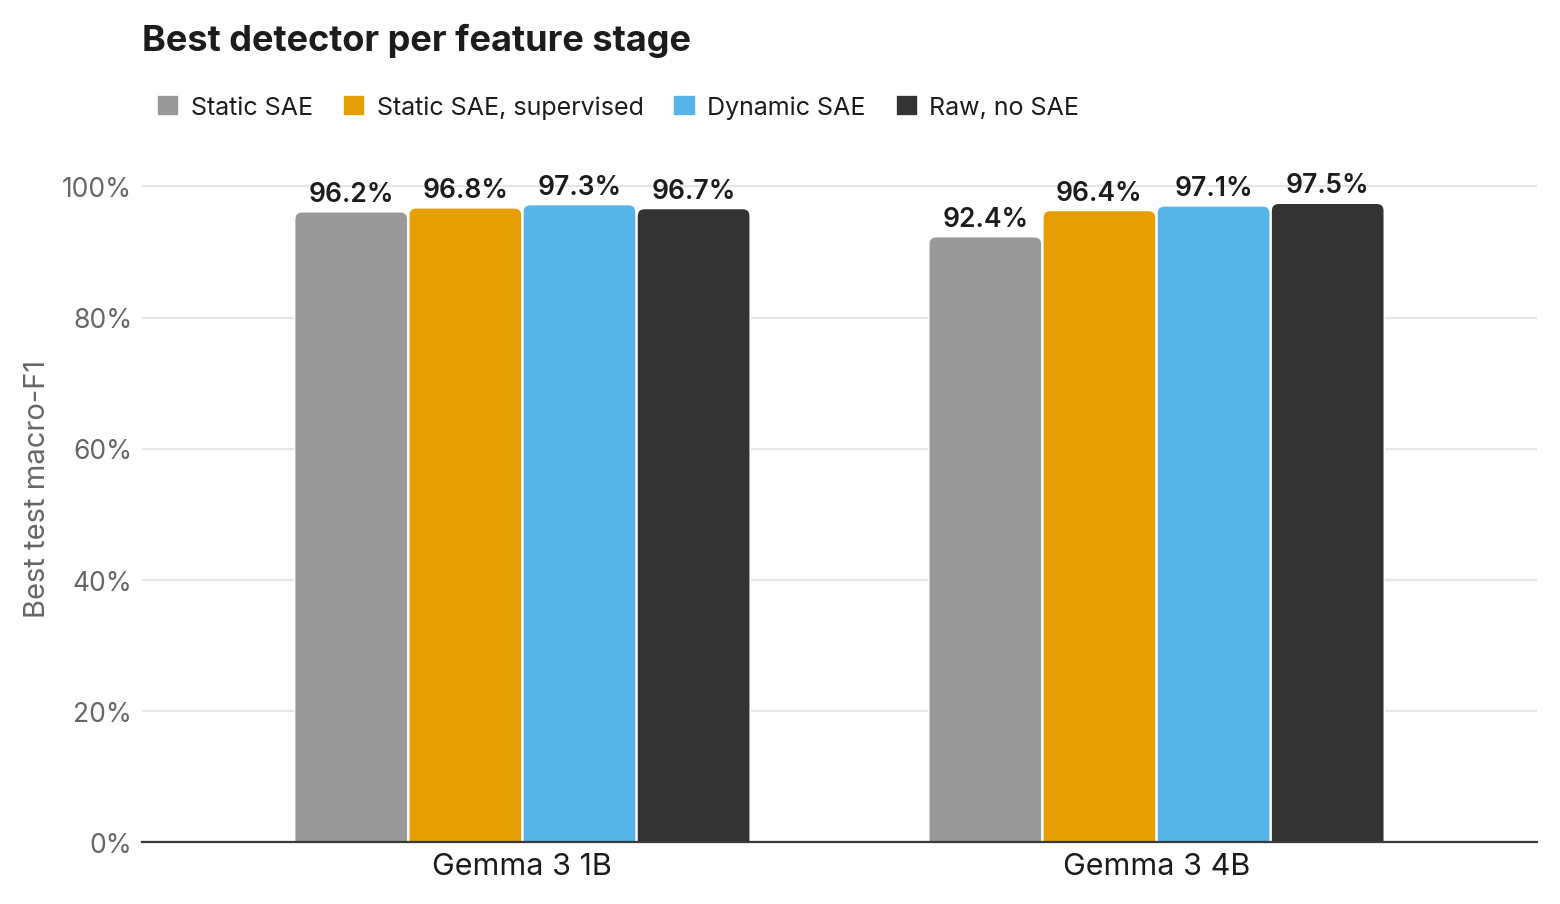
We tested whether small probes on sparse autoencoder features can catch Gemma 3 drifting off topic while it writes, labelling every token with one of seven business topics. Raw hidden states do as well as SAE features; what the SAE buys is a smaller detector whose inputs have names.

Rishikesh Mallagundla · Oct 14, 2026 · 54 min read Read the log
Earlier
Research

Pretraining Dense Models: A Research Log

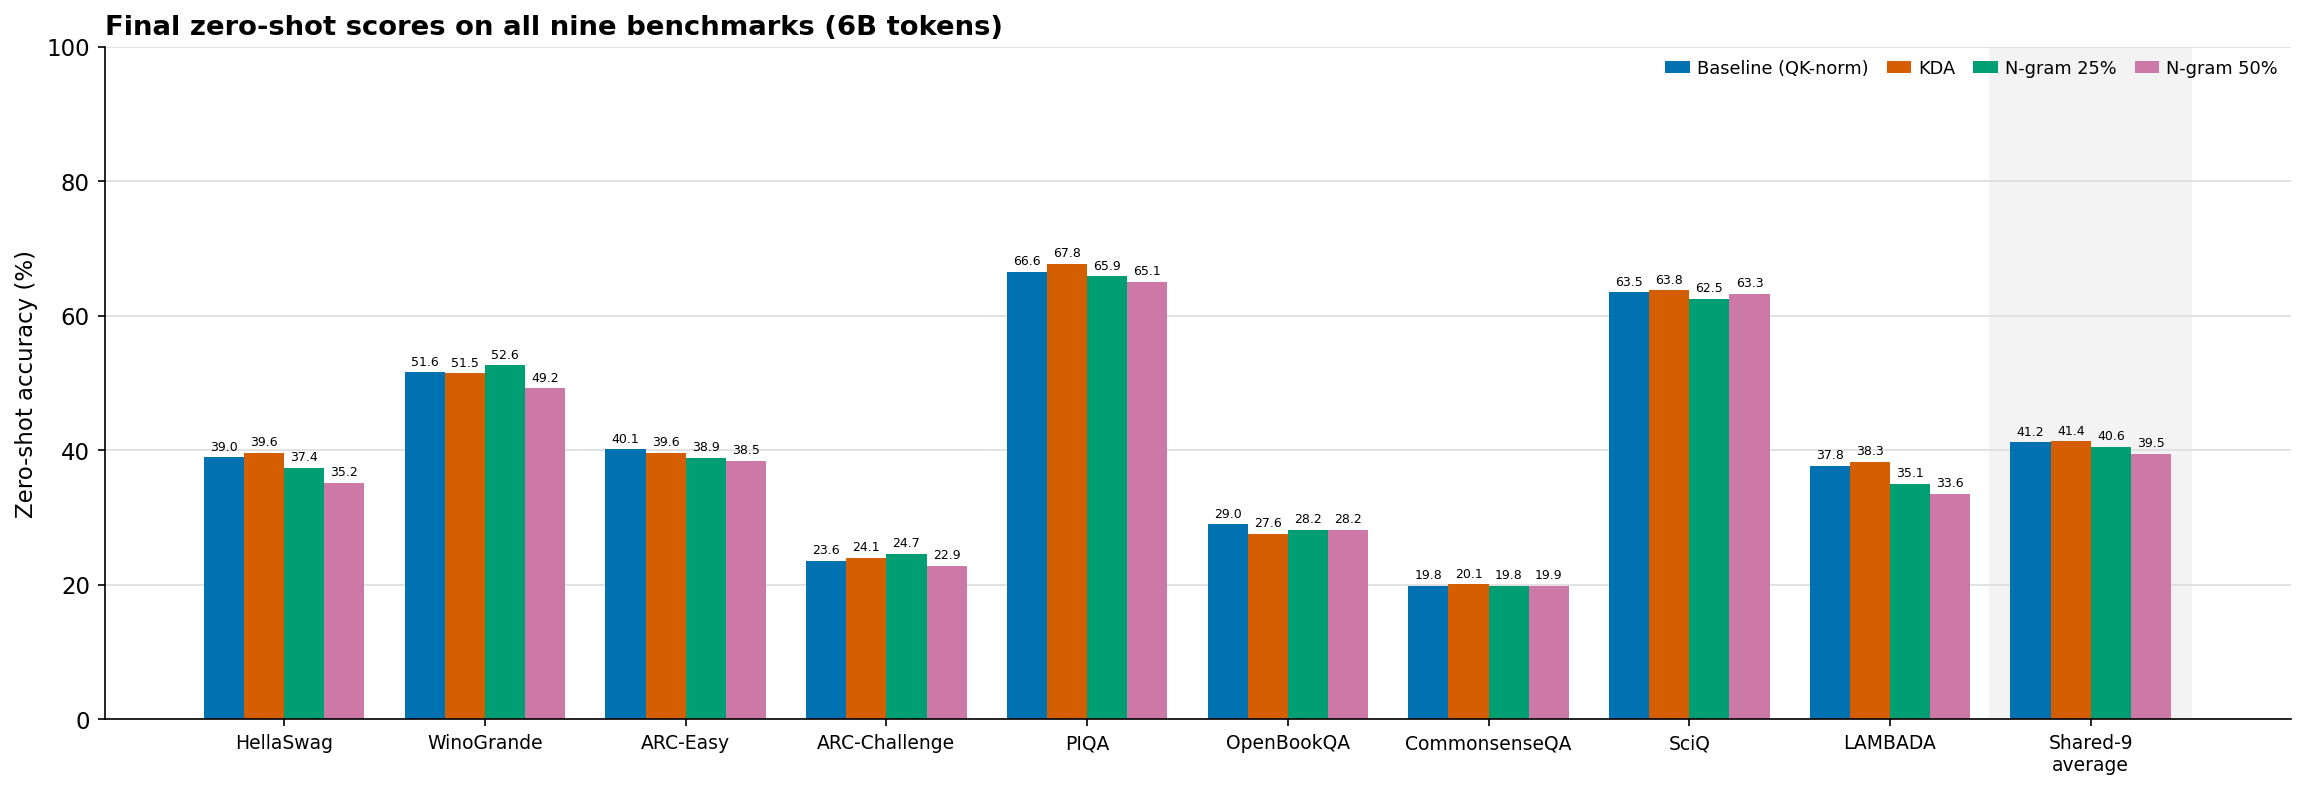
We pretrained four dense 1B-parameter checkpoints on 6B FineWeb tokens to test Kimi Delta Attention and LongCat n-gram embeddings, then compared grafting, pruning, 4-bit quantization, and downstream NER fine-tuning.

Rishikesh Mallagundla 56 min read Read
Research

Building LLM Guardrails with SAEs

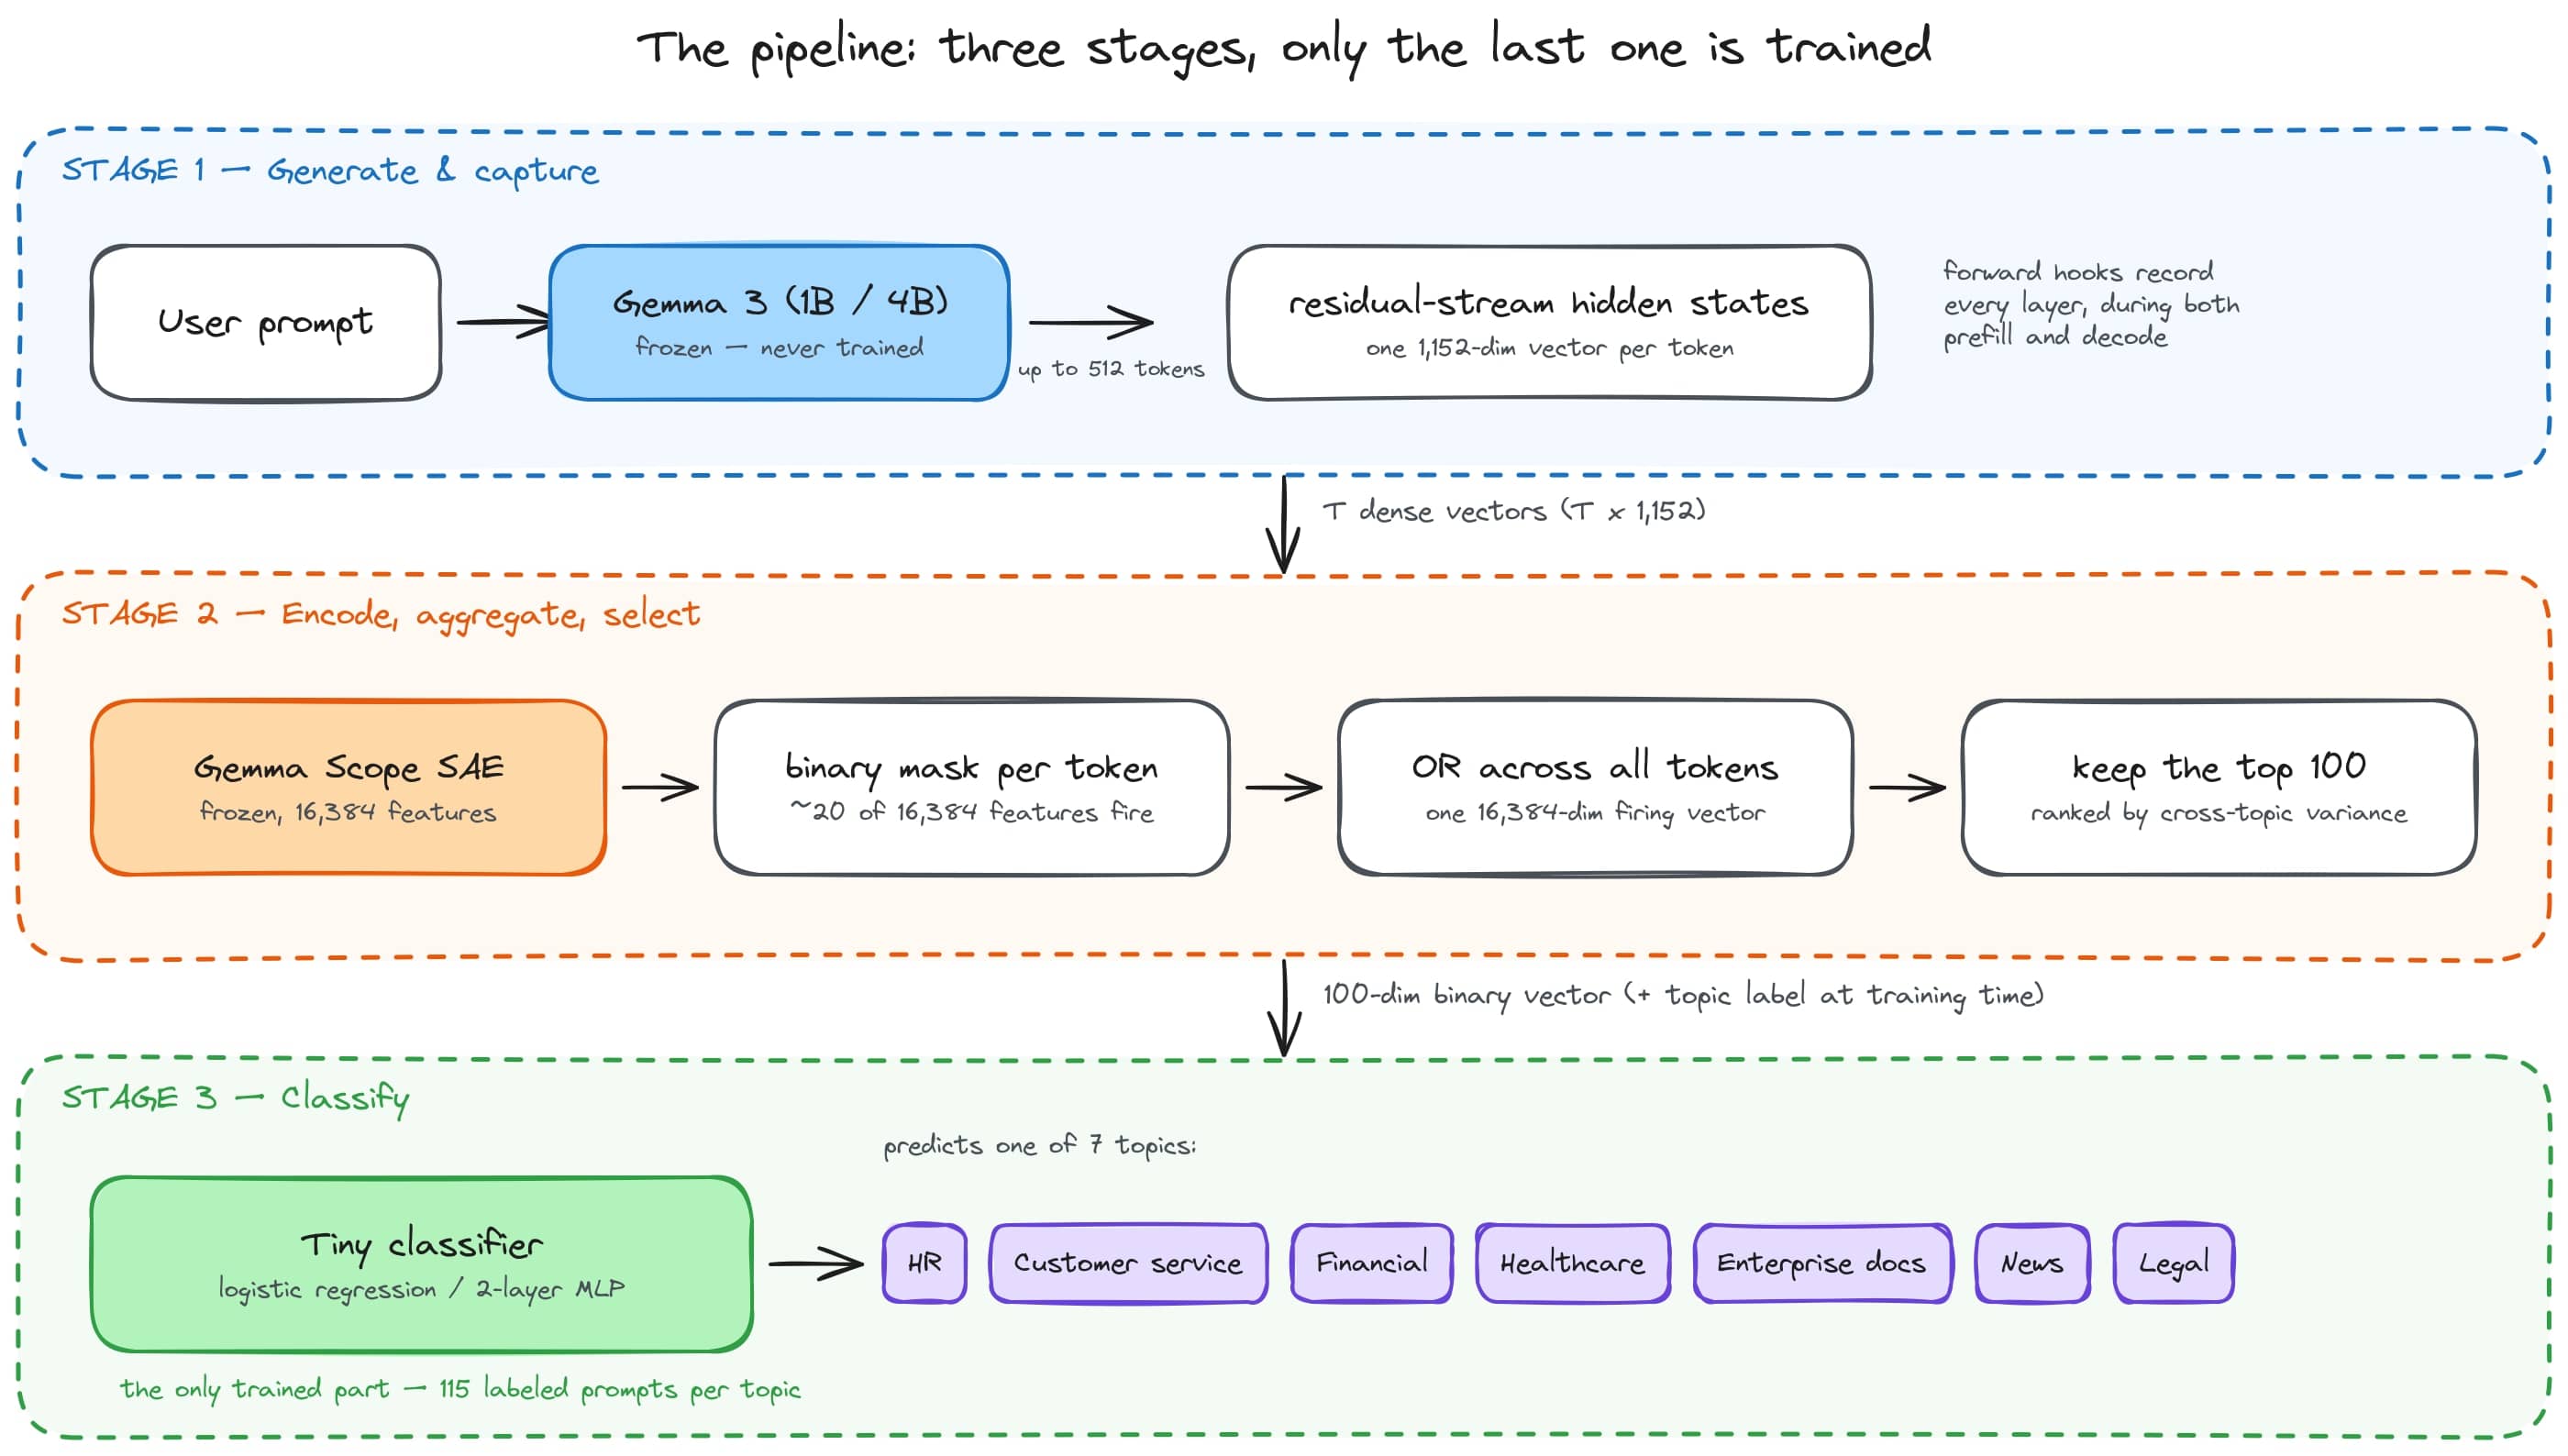
We wanted to test whether sparse autoencoders can replace a dedicated topic classifier in an LLM guardrail stack, reading the topic directly from the model's internal activations instead of running a second model over its output text.

Rishikesh Mallagundla 31 min read Read
Research

Building Simula: Our Synthetic Data Generation Library

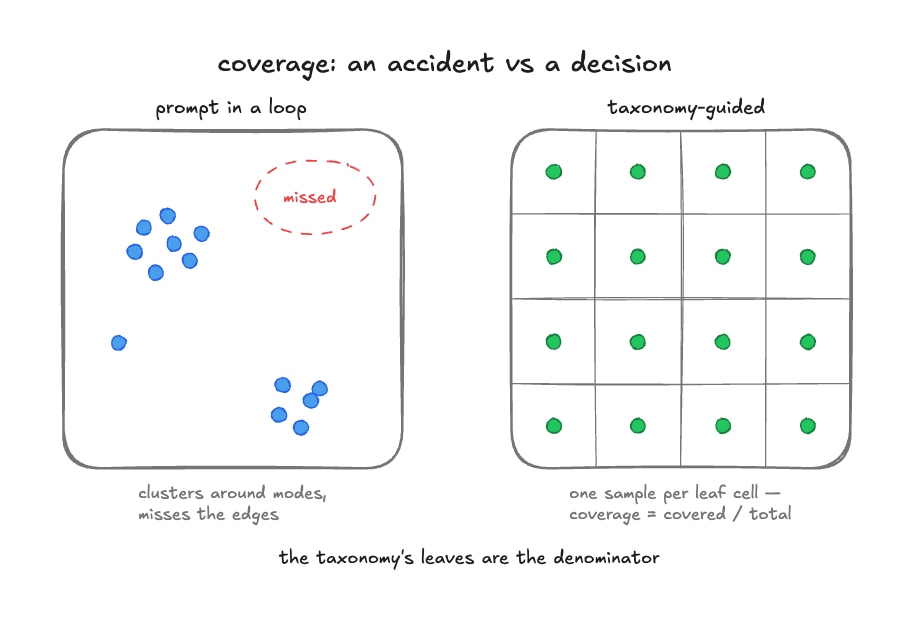
Why we built simula, a compact CLI-first Python library for schema-shaped and free-text synthetic data generation — taxonomies as coverage maps, weighted sampling strategies, generator–critic loops, and the lessons from generating tens of millions of tokens across client projects.

Pranav Patel 31 min read Read
Research

LaCo Layer Pruning for Qwen3-8B: Our Research Log

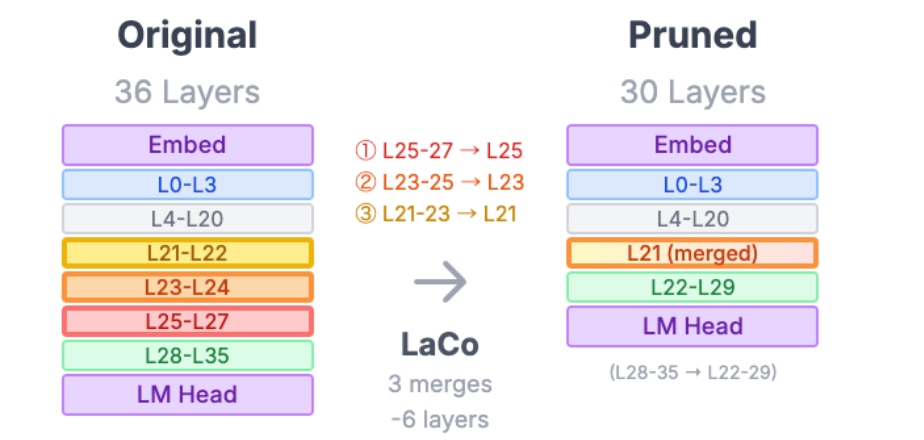
How we implemented LaCo layer pruning on Qwen3-8B-Base, compressing 36 layers to 30 with 16.7% size reduction while retaining 78–94% of reasoning capabilities — covering the paper-vs-implementation discrepancy, hyperparameter tuning, a critical "knowledge cliff" at 22% compression, and full benchmark results without post-training.

Juhi 24 min read Read
Diffusion Models

Latent Consistency Models: Training Fast Diffusion Models

A research log of our work on training Latent Consistency Model with LoRA adapters for Stable Diffusion 1.5 to reduce generation from 25-50 denoising steps to 4-6 steps, leading to massive cost and time savings with quality trade-offs, setup details, and evaluation results.

Juhi Singh 24 min read Read