Synthetic data generation
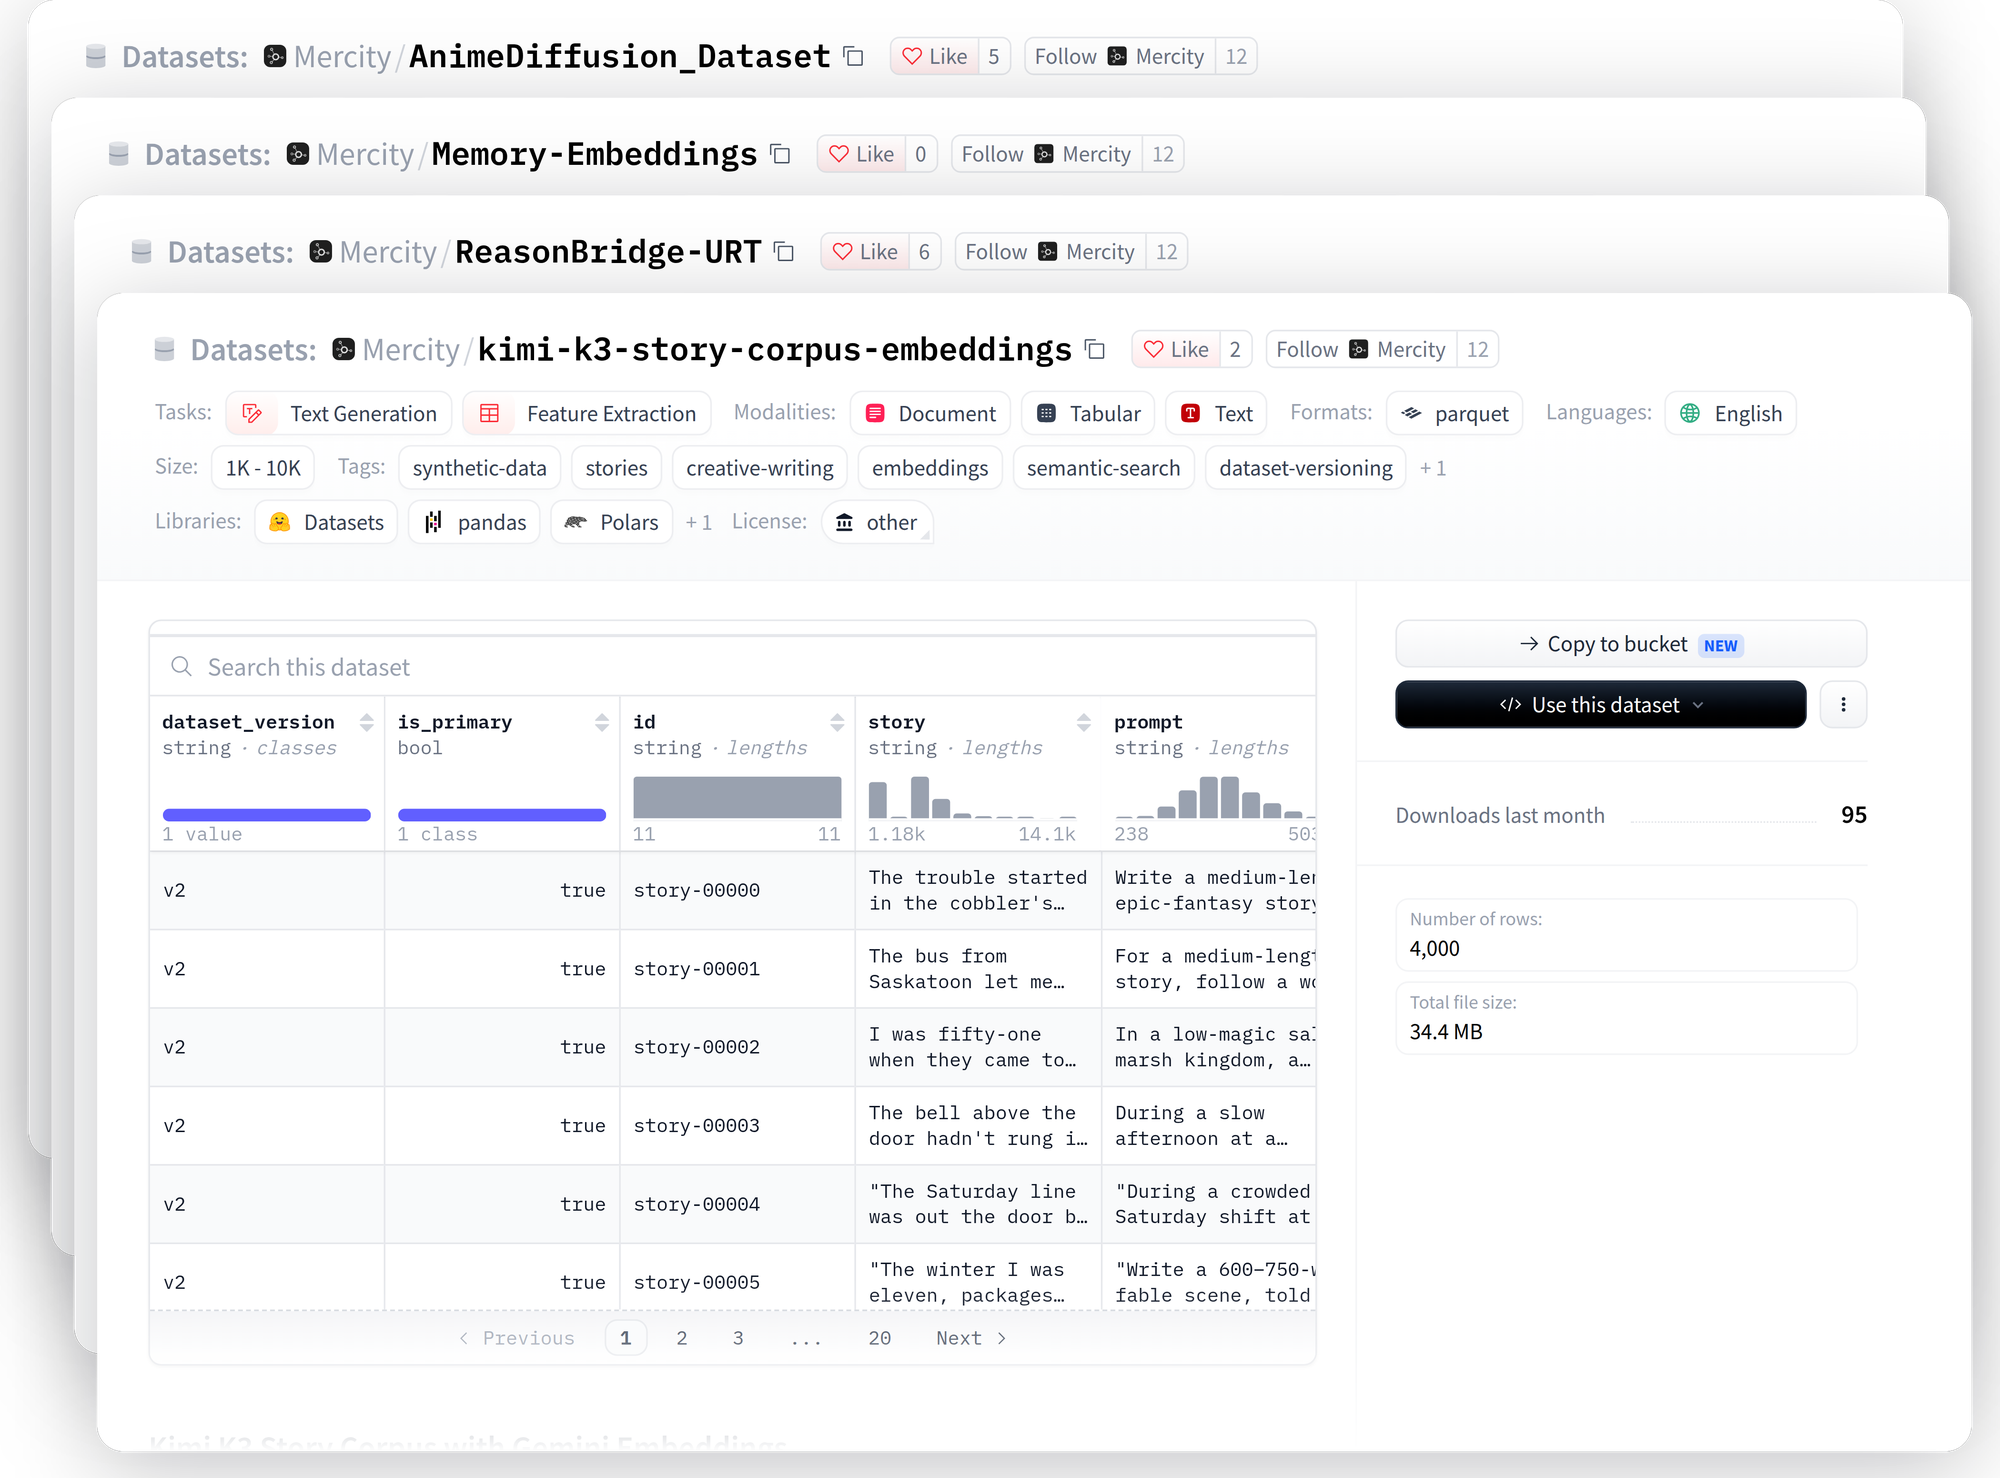
Over the years we have generated hundreds of billions of tokens of synthetic data and trained models on it. More than half our projects need a pipeline built for that specific data, with our open‑source library Simula covering part of the work. Every dataset ships with its generation code, filters and coverage report.